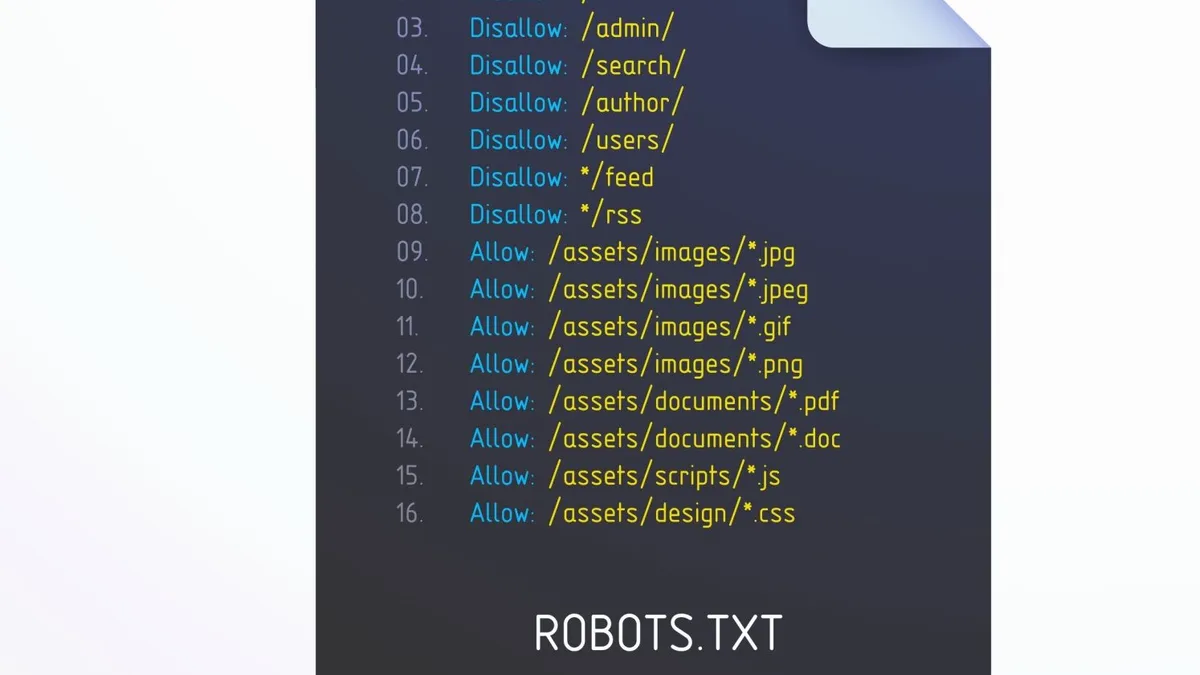
Robots.txt Rules for Search and AI Crawlers, Explained Practically
A practical walkthrough of robots.txt rules that protect crawl budget while keeping valuable pages open to search engines and AI bots.
 Pierre Silva
1 min read
Which Robots.txt Rules Should You Actually Use?
This Search Engine Journal guide explains how robots.txt directives work in practice, and how Google chooses between conflicting rules when a bot has its own group. The author walks through the two wildcards the format supports, the case-sensitive handling of URL paths, and the rule that the more specific match wins. Most of the piece is worked examples: blocking internal search results, trimming faceted filter URLs, excluding PDFs, keeping a sign-in page indexable while hiding its subpages, and protecting scripts that rendering depends on.
For brand builders, the value is in the caution. A careless disallow can quietly hide product pages from search and from AI answer tools, while a missing one lets large catalogues waste crawl activity. Developers, SEO leads and ecommerce managers should read it before touching their live file. Pair it with a test in Search Console so each rule is checked against the URLs you actually want kept open.
Source: searchenginejournal.com · Originally published